The world is about to run on flops.
GPU Boom stands up large-scale GPU clusters on a predictable timeline and rate. We own the value chain from the dirt to the rack. And when we're not building it, we get it financed.
How we help
Two ways to get compute built.
Either we build and run it for you, or we bring the capital that lets someone else build it. Often both.
Build · Deploy · Operate
01We stand it up.
Large-scale GPU clusters, delivered in a short period of time on a predictable timeline and rate. We're vertically integrated from the dirt to the rack, so there's no chain of third parties between you and a running cluster.
- 16–256 node clusters
- Tier III, 100% US-based
- 24/7/365 NOC and onsite smart hands
Source · Structure · Close
02We get it financed.
When we're not procuring, deploying or managing the compute ourselves, we help get the deal done. We match capital to opportunity and bridge the gap between capital markets and technical operators.
- Debt facilities and project finance
- Matchmaking lenders with operators
- Success-based fixed fee only
Act I
Every age runs on something.
Timber. Coal. Oil. Silicon.
This one runs on compute.
Every model, every agent, every breakthrough starts as a job waiting for a GPU.
The chips exist. The power exists.
What's missing is someone who owns the whole chain: the land, the power, the building, the racks, and the capital to pay for it.
We stand it up.
Our buy box
What we stand up.
We focus on one kind of deployment and do it well. If your requirement fits these six lines, we can usually confirm capacity, price and a ready date within a day.
Cluster size
16–256nodes
128 to 2,048 GPUs per cluster on a non-blocking InfiniBand fabric.
- HGX H100, H200, B200, B300
- 8 GPUs per node
- 3.2 Tb/s InfiniBand per node
Agreement term
24–48months
Long enough to price well, short enough to stay current with the hardware cycle.
- 24, 36 or 48 month terms
- Rate locked for the full term
- Expansion at your contracted rate
At signing
30%deposit
A 30% deposit reserves the cluster. The balance is billed monthly once the cluster passes acceptance.
- Deposit secures hardware and space
- Monthly billing after acceptance
- One master agreement
Location
100%US-based
Every cluster sits in a US facility. Your data and your hardware stay under US jurisdiction.
- East, Central, South and West regions
- Facility named before you sign
- US-based operations team
Operations
24/7/365NOC + smart hands
Our NOC watches every node around the clock, with onsite smart hands for swaps, cabling and resets.
- Proactive GPU health monitoring
- Onsite smart hands, every day of the year
- Hardware swaps under SLA
Datacenters
Tier IIIfacilities
Concurrently maintainable facilities with layered physical security. No exceptions.
- N+1 power and cooling, dual utility feeds
- 24/7/365 onsite armed security
- Biometric access, mantraps and full CCTV
Tier III, and then some.
Every facility we use is Tier III or higher, concurrently maintainable, with SOC 2 Type II and ISO 27001 attestations, fire suppression, and security staff on site around the clock.
Vertically integrated
From the dirt to the rack.
We own the value chain from start to finish. That's what lets us commit to a timeline and a rate, and stay flexible when your plans change.
- 01
Land
Sites selected and controlled for power, fiber and expansion.
- 02
Power
Utility interconnects and on-site capacity secured early.
- 03
Facility
Tier III buildings, cooling and physical security.
- 04
Hardware
GPU, network and storage procurement without allocators in the middle.
- 05
Integration
Racking, cabling, fabric and burn-in by our own team.
- 06
Operations
24/7/365 NOC and onsite smart hands for the full term.
| Stage | GPU Boom | Typical provider |
|---|---|---|
| Land and power | Controlled by us | Leased through a colocation provider |
| Facility | Built and run in-house | Third-party developer |
| GPU allocation | Procured directly | Waits on allocators and resellers |
| Integration and deployment | Our own team | Outsourced systems integrator |
| Operations | Our NOC and smart hands | Another contract, another SLA |
| Timeline | One contracted ready date | Depends on 4–6 vendors lining up |
| Rate | Fixed for 24–48 months | Marked up at every layer |
Our facilities
See where your cluster lives.
This is what vertically integrated looks like: our own campus, our own power, our own cooling and our own data halls. No colocation middleman.
Campus · Cooling · Power · Data halls
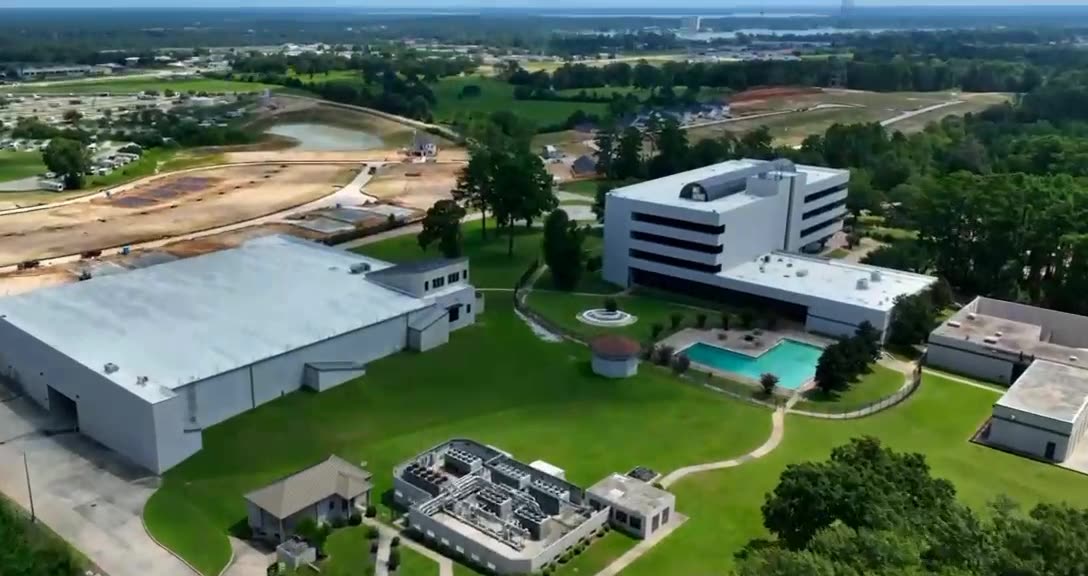
Campus
Room to grow: land, buildings and power under one roof line.
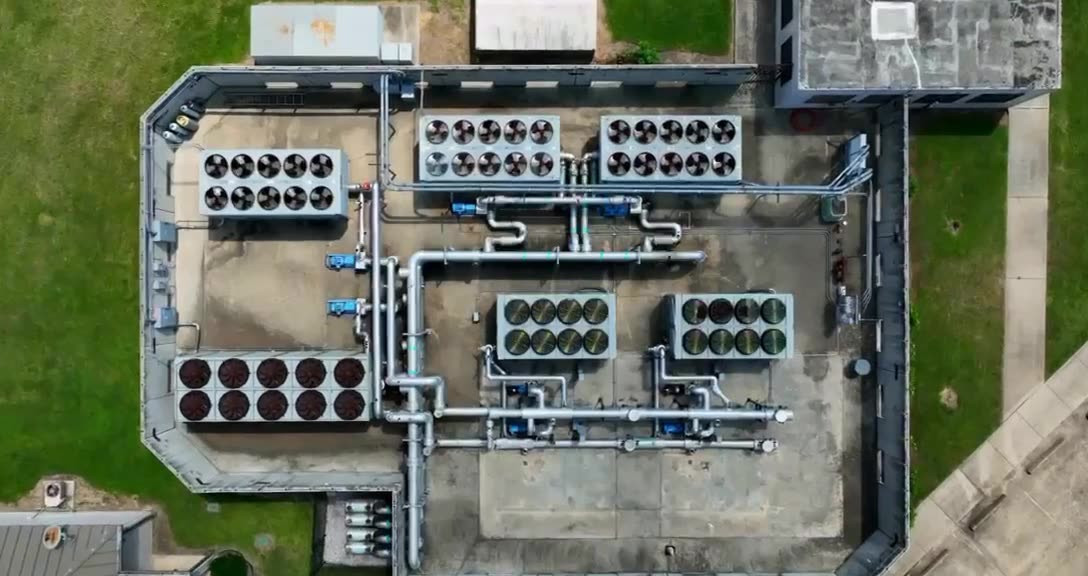
Cooling plant
Heat rejection sized for dense GPU racks.
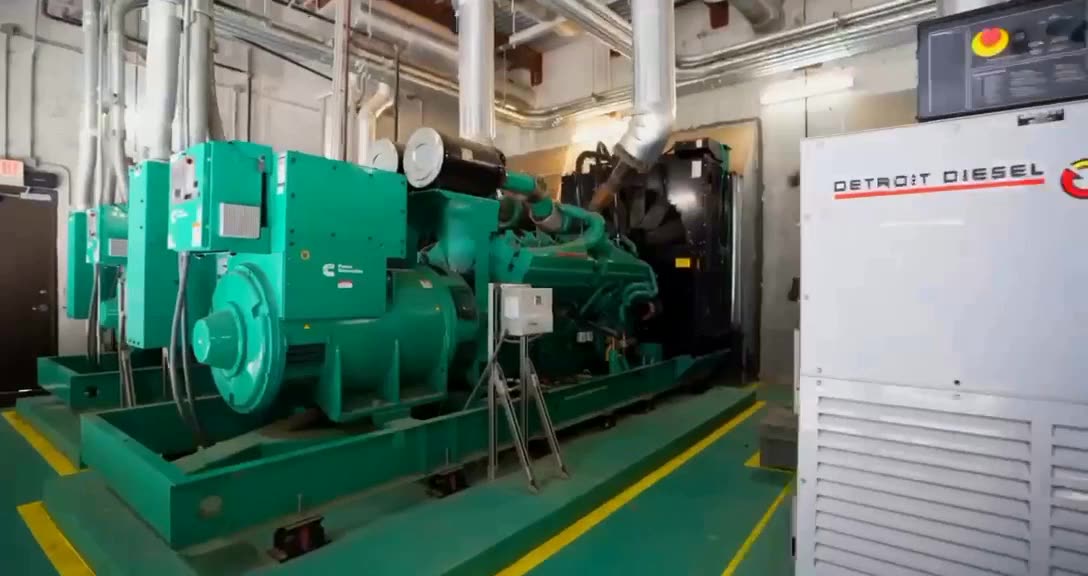
Backup power
On-site generation behind every data hall.
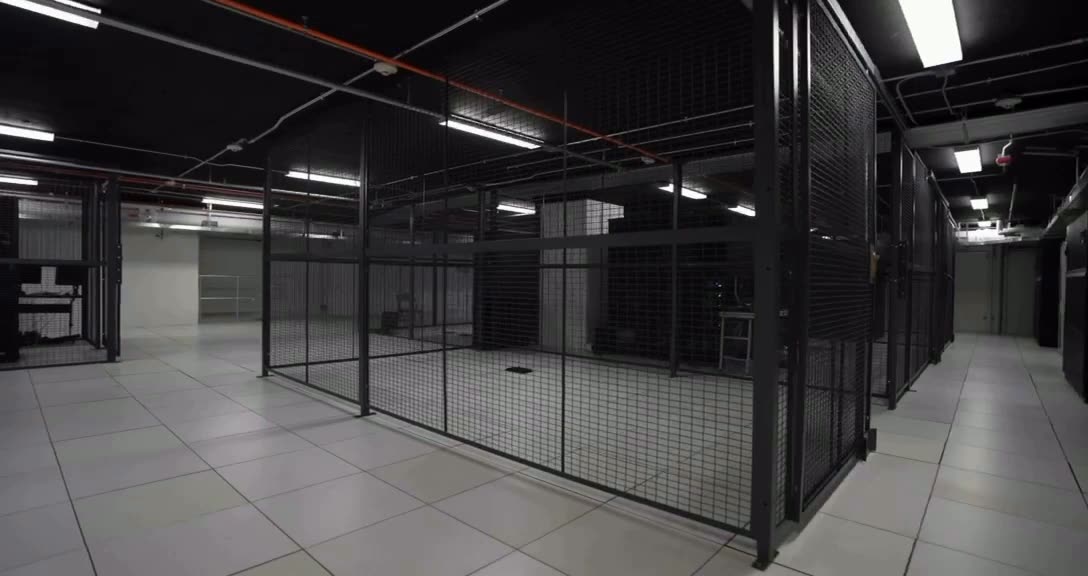
Secured data halls
Caged white space on raised floor.
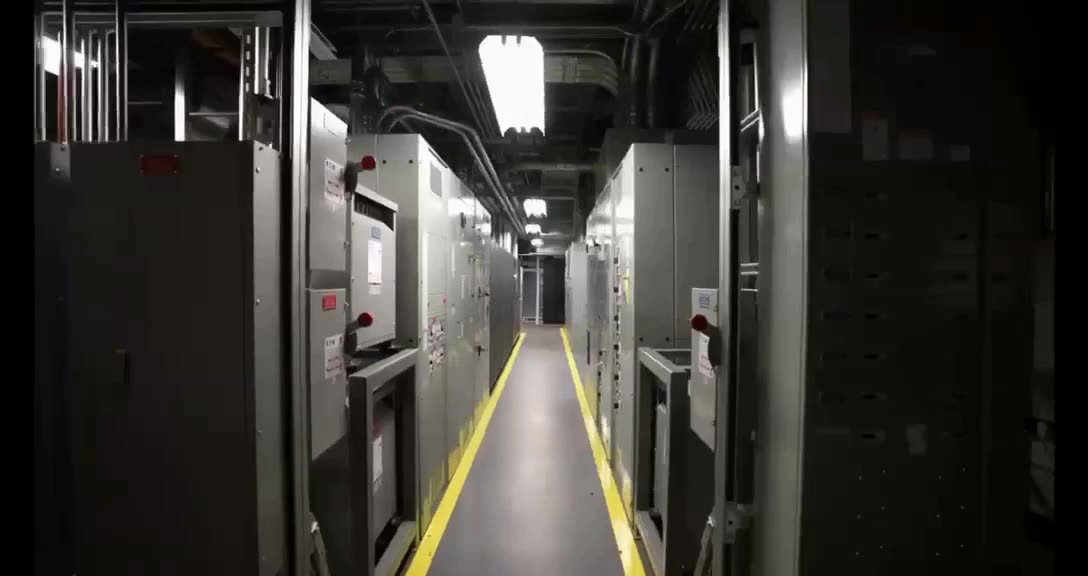
Mechanical corridors
Power and cooling infrastructure, maintained live.
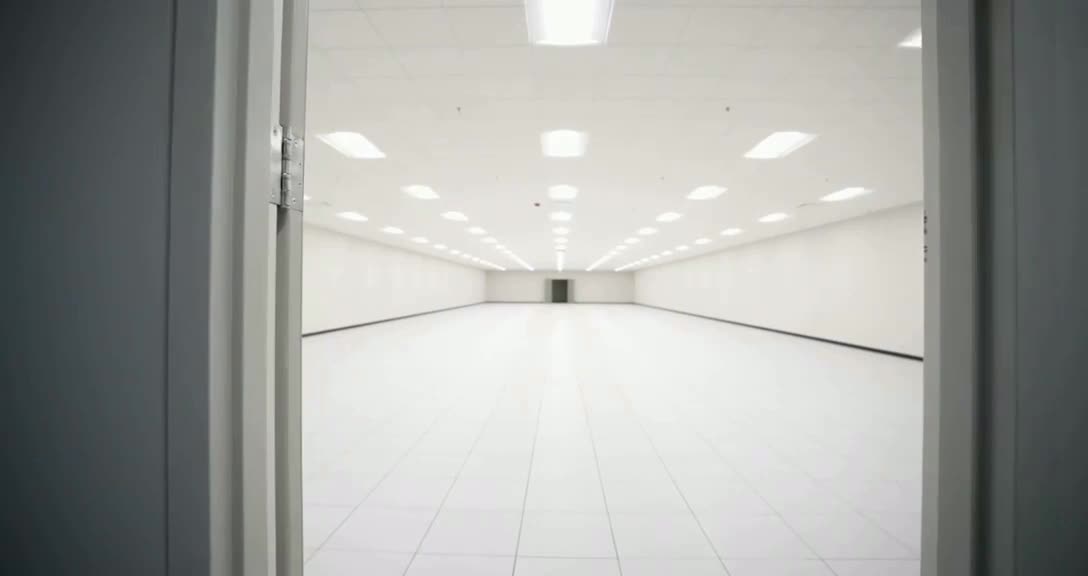
Ready white space
Halls ready to fit out for the next cluster.
Capital advisory
We get the deal done.
Capital markets and technical operators speak different languages. We bridge the gap: sourcing capital, matching it to the right opportunity, and placing the debt facilities that get projects built.
How we're paid
Success-based fixed fee. Nothing else.
No retainers, no hourly billing. If we place the debt facility or the relationship that leads to a successful project, we earn a fixed fee. If the deal doesn't close, we don't get paid.
We eat only what we kill.
- 1
Source
We find the projects worth financing, and vet the operators, sites and hardware behind them.
- 2
Structure
Debt facilities, project finance and GPU-backed lending, shaped around real contracted demand.
- 3
Match
We put the right lenders and funds in front of the right operators, and translate between the two.
- 4
Close
We stay on the deal through diligence and close. That's the only point at which we get paid.
For operators and developers
You have the site, the power or the customer. We find the capital to build it.
For lenders and funds
Vetted GPU infrastructure deal flow, from people who know how it gets built.
Foundation services
Everything beneath your models.
Compute, storage, network and security, stood up as one environment. You bring the workload. We bring the foundation.
- 01
Compute · GPUs
Compute fabric
Capacity planning, workload placement and dedicated HGX hosts, from a 16-node cluster to 256 nodes and 2,048 GPUs.
H100 → B30016–256 nodesBare metal or K8s - 02
Storage · Data
Storage plane
High-throughput parallel storage next to the GPUs, with snapshots, checkpoint paths and fast recovery.
NVMe tiersCheckpointingSnapshots - 03
Network · Fabric
Network core
Non-blocking InfiniBand inside the cluster, private routing and dedicated bandwidth out of it.
3.2 Tb/s IBPrivate routingRedundant uplinks - 04
Security · Operations
Security shell
Isolated tenancy, access boundaries, 24/7/365 NOC monitoring and onsite smart hands. Every layer observable and recoverable.
Tenant isolation24/7/365 NOCSmart hands
Available capacity
The board.
Clusters inside our buy box, across Tier III facilities in the US. Updated daily.
| GPU | Size | Region | Term | Ready | From / GPU-hr | Action |
|---|---|---|---|---|---|---|
| B200 HGX | 64 nodes · 512 GPUs | US-East | 24–48 mo | Now | $3.89 | Request → |
| H200 HGX | 128 nodes · 1,024 GPUs | US-West | 24–36 mo | Now | $2.69 | Request → |
| B300 HGX | 32 nodes · 256 GPUs | US-Central | 36–48 mo | Q1 2027 | $4.19 | Request → |
| H100 SXM | 16–256 nodes | Multi-region US | 24–48 mo | Now | $2.09 | Request → |
| B200 HGX | 256 nodes · 2,048 GPUs | US-South | 48 mo | Q2 2027 | On request | Request → |
Sample listings for preview purposes. Final pricing depends on term, size and facility.
Pricing
Priced per GPU-hour. Locked for the term.
Every rate includes the node, the fabric, local NVMe, Tier III space and power, 24/7/365 NOC and onsite smart hands.
NVIDIA
H100
80 GB HBM3
from$1.89/ GPU-hr
36-month term
The workhorse. Proven for training and inference.
- Most requested
NVIDIA
H200
141 GB HBM3e
from$2.49/ GPU-hr
36-month term
More memory per GPU for long context and big batches.
NVIDIA
B200
192 GB HBM3e
from$3.59/ GPU-hr
36-month term
Blackwell throughput for frontier-scale training.
NVIDIA
B300
288 GB HBM3e
from$4.19/ GPU-hr
36-month term
The newest silicon, for the biggest models.
Cluster estimate
32 nodes × 8 GPUs × $2.49 × 730 h
- Monthly
- $465,331
- Contract value · 36 months
- $16,751,923
- 30% deposit at signing
- $5,025,577
GB200 / GB300 NVL72 racks: price on request →
Our process
From first call to ready for service.
A clear, three-phase path. You always know what happens next, who owns it, and when.
Phase 1
Qualify- 1
Sign a mutual NDA
We sign an MNDA before the first call, so both sides can share specifics openly.
- 2
30-minute discovery call
For qualified buyers only, after initial validation. We cover:
- Cluster size, requirements and desired outcome
- Term, hourly rate and deposit %
- Region and designated data center
- Target ready-for-service (RFS) date and growth plan
Phase 2
ContractStarts once initial terms are agreed.
- 3
Final technical and legal review
MSA review, reference architecture, deployment plan and timelines, signed off together.
- 4
Financial profile review
We review the financial profile of the entity signing the contract.
We only support creditworthy, bankable companies.
- 5
Signing and deposit
Contracts are executed and the deposit is paid, reserving hardware and space.
Phase 3
Stand up- 6
Delivery and rack-and-stack
Hardware ships to the designated data center, where our data center team racks, cables and powers it.
- 7
Network, storage and validation
We bring up connectivity and the InfiniBand fabric, integrate storage, then run burn-in and acceptance testing.
- 8
RFS and handoff
The cluster is declared ready for service and handed off to your team for offtake.
Who qualifies
Creditworthy, bankable counterparties only.
Every contract is backed by real infrastructure and real capital, so we review the financial profile of the signing entity before we commit. It protects your deployment, our lenders and the timeline.
Acceptance testing before handoff
- PASSDCGM Level 3 diagnostics
- PASSHPL & HPL-MxP
- PASSNCCL all-reduce
- PASSNVLink bandwidth
- PASS48-hour burn-in
- PASSStorage under load
Who it's for
Every side of the market.
AI teams that need compute, NEO Clouds that resell it, and the operators and capital behind it.
AI companies · labs · enterprises
Your runway is for research. Not for building datacenters.
Get a dedicated 16 to 256 node cluster in a Tier III US facility, operated around the clock, at a rate locked for 24 to 48 months.
Stand up compute- 128 to 2,048 GPUs per cluster
- 30% deposit, then monthly
- Engineers on Slack, not a ticket queue
FAQ
Straight answers.
Something else? Email us at hello@gpuboom.com
Creditworthy, bankable companies. Before signing, we review the financial profile of the entity that will sign the contract. Discovery calls are for qualified buyers, after initial validation and a signed MNDA.
Clusters of 16 to 256 nodes (128 to 2,048 GPUs), on 24 to 48 month agreements, with a 30% deposit, in 100% US-based Tier III facilities, backed by a 24/7/365 NOC and onsite smart hands.
We control the chain from the dirt to the rack: land, power, the facility, hardware procurement, integration and operations. With no colocation provider, allocator or integrator in between, we can commit to a ready date and a rate, and adjust when your plans change.
A success-based fixed fee, and nothing else. No retainers or hourly billing. If we place the debt facility or the relationship that leads to a successful project, we earn the fee. If it doesn't close, we don't.
Everything between a signed agreement and a running job: sourcing the GPUs, the facility, power and cooling, the InfiniBand fabric, storage, networking, security, burn-in testing, and 24/7/365 operations for the term.
Phase 1: sign an MNDA, then a 30-minute discovery call on cluster size, term, rate, deposit, region and RFS date. Phase 2: final review of the MSA, reference architecture and deployment plan, a financial profile review, then signing and deposit. Phase 3: we ship, rack and stand up the hardware, bring up network and storage, test it, and hand it off at RFS.
The deposit is due at signing and reserves the hardware and the space. The balance is billed monthly, starting once your cluster passes acceptance testing.
Tier III facilities are concurrently maintainable: power and cooling have N+1 redundancy, so maintenance happens without downtime. We also require 24/7/365 onsite security, biometric access, mantraps, full CCTV coverage, and SOC 2 Type II and ISO 27001 attestations.
Only in the United States. You choose the region (East, Central, South or West), and we name the exact facility before you sign.
That's outside our buy box. Talk to us anyway: if we can't do it well, we'll tell you who can.
Our NOC sees it first. Onsite smart hands swap failed hardware under SLA, and downtime beyond the SLA is credited back automatically.
You can expand inside the same agreement at your contracted rate. If you need less, we can remarket the capacity on your behalf.
Get access
The next breakthrough needs a cluster. Let's stand it up.
Need a cluster stood up, or capital to build one? Tell us what you're working on and we'll come back within one business day.
Lender or fund? See capital advisory →